Category Archives: Problems

Teaching an LLM a little Jiu Jitsu

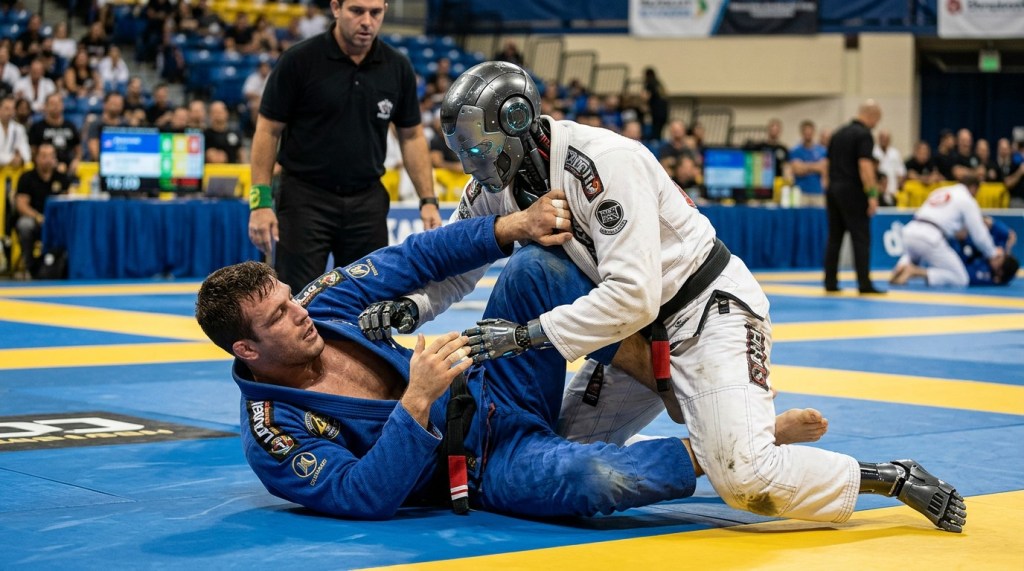
A Brazilian Jiu-Jitsu match is in progress, featuring two competitors on a blue mat. One fighter, wearing a blue gi, is positioned on the bottom while the other, in a white gi with robotic elements, is attempting to gain control. A referee oversees the match, with spectators in the background.

Earlier this year, my colleagues at Relational AI helped AT&T build LLM models focused on Telecom called Otel and push it to the top of the leaderboard. I wish I could tell you all about it, but I wasn’t on the team. No worries though, you can read all about on the links above. Instead I’m going to tell you about training an LLM focused on Brazilian Jiu Jitsu. The idea is to ask it all kinds of dumb beginner questions and have it provides great answers. All without getting frustrated or telling you to focus on the fundamentals before trying flying armbars. Now, I wish I could just sign up Claude to our local school, fast forward 10 years and be done, but LLMs can’t learn that way. Large Language Models need Language, they need Text.

Luckily there are thousands of “Instructionals” (video classes teaching a topic or technique) of usually high quality and thousands of YouTube videos of varying degrees of quality we can use as our starting point. While kid classes pay the bills for local schools, it turns out middle aged men are the target audience of the instructional market. I had already purchased over 50 instructionals on BJJ Fanatics, but that wasn’t nearly enough, I had to use the Jozef Chen method and got a lot more. I also got some competition match clips that were narrated from youtube and downloaded them using yt-dlp.

Everyone is short on attention these days, so this is the AI:DR version for you to replicate this for your own video or document library:

  1. Clean phonetic transcription errors and prepend Contextual Retrieval headers ([Context: Author — Source | Category | Tags]) before embedding.
  2. Build an explicit Knowledge Graph mapping canonical tags, cross-school synonyms, parent-child tag hierarchy, and mutual-exclusivity rules.
  3. Audit video keyframes with CLIP + a Vision-Language Model so silent physical demonstrations become searchable [Visual Demonstration] chunks.
  4. Mine timestamped links from your existing docs to fine-tune an ONNX Cross-Encoder Re-Ranker (bge-reranker-base) with 5-way listwise loss.
  5. Synthesize a 3-Track SFT dataset (6-excerpt RAFT with distractors + diagnostic Go/No-Go gates + Knowledge Graph lineage/rules) and gate it with an automated <0.35% 7-gram linter.
  6. Run 2.5x Decision-Weighted QLoRA SFT followed by Zero-Extra-VRAM PEFT DPO (with model.disable_adapter(): + 0.15 NLL anchor) on a single GPU.
  7. Verify against a rubric-scored domain benchmark and deploy on volume-backed vLLM serverless.
Continue reading →
Tagged , , , , ,

Eating our own tails

If we are able to build mountains of code in days instead of months. Then we don’t need 100 developers per app, but just a handful…. say 7. If we only need those 7, then we only need to buy 7 AI subscriptions. If we only buy 7 subscriptions instead of 100, then we pay the AI companies a tiny amount of money, so they don’t need all those chips, which means they don’t buy from Nvidia and Micron and friends. Right?

So 93 people are out of a job and valuations collapse? Please tell me I’m wrong.

Tagged , , ,

Hey Database! Go Fine Tune Yourself

Everyone expects AI prices to go down in the long term. But in the short term, we have three things going on. Token prices keep dropping, hurray for that. Subscription fees are going up and dumping their all you can eat plans for volume based pricing. There more you use, the more you pay. I guess that’s fair. Third, hardware component pricing is going up and big companies are borrowing billions to build the greatest and latest AI data centers. What’s going on? Are we in the pets.com era of selling $40 dollars worth of dog food for $20 bucks and making it up in volume? The real question is, how do we close this giant chasm of a value gap?

Molham Aref argues that enterprises must make agents smarter and cheaper. We have to solve two problems at the same time: making agents smart enough to handle real business decisions, and ensuring they are cost-effective enough to scale enterprise-wide. It sounds simple enough on the surface, but… it’s not. I’m going to talk about one of the ways we are doing that. But before I start, about six months ago, Greg Diamos and Naila Farooqui at RelationalAI wrote a blog post “Introducing Superalignment for Relational Databases“. If you haven’t read it yet, please take the time to do it now or you may be a little lost on what follows. There is a line in there people sometimes overlook, even thought it’s literally highlighted in bold:

The training dataset is the database itself.

Continue reading →
Tagged , , , , , , ,

Decision Graphs

About eight years ago, I wrote a little blog post on dynamic decision trees. If you have the time, go back and read that and the follow up posts on the subject. If not, I’ll summarize. Instead of building a Rules Engine to make decisions, I built a dynamic traverser that evaluates logic on the fly. This enables us to change how the decisions are made any time. We can also version the trees as we change it and create completely new trees for any complex decision making. If we don’t have enough information to get to a conclusion, it doesn’t give up or make something up, instead it asks us a question we must answer to continue down the path.

I bring up this relic from the past because I’m still trying to wrap my head around the value of “Context Graphs”. Which are supposed to be graphs that capture the how, when and why decisions were made instead of what decision was made. The idea being to capture “decision traces” which then allow an AI agent to see precedents (how similar problems were solved) and apply those same rules to new situations. The first decision traces would be made by people, and then the agents could learn and take it from there. So every time you want a decision answered, your agents would read all the previous decisions, analyze them, and make a new decision. But why? If we made a policy change, would the AI agents now ignore all the previous decisions and utilize the new policy? Would we have to repopulate the graph with human made decisions following the new policy so the agent understood there was a change?

Continue reading →
Tagged , , , ,

Cleansing your Neo4j Aura

Last week I was helping out a user who was seeing lots of error messages in their application logs when connecting to Neo4j Aura. So I did like any good developer and I asked the all knowing all powerful google how to cleanse your Aura, and guess what it told me…

Continue reading →

Tagged , , , , , , , ,

Graphs and Pyramids

Question: Do you want to get Rich?
I’ll answer for you: “Yes!”

Follow along with this blog series and if it doesn’t make you rich, you can go back to your youtube videos, you can go back to watching Tiger King on Netflix, you can go back to your crappy life. Let’s continue.

Question: Are you poor? dumb? ugly? do you make bad decisions?
I’ll answer for you: “Yes!”.

If you were not poor, you would be on a yacht in Ibiza and not reading my blog. If you were not dumb you would be doing whatever it is smart people do, I wouldn’t know but I’m pretty sure it’s not reading my blog. If you were not ugly you would be in Paris or Milan murdering the runway instead of reading my blog. If you didn’t make bad decisions you wouldn’t have decided to read my blog which just made you feel sad about your life. See where I’m going with this?

Continue reading →

Tagged , , , , , , , , , ,

Building a Chat Bot in Neo4j Part 3

In part one, we learned to listen to our users, in part two we began learning how to talk back. Before we go any further in to the stored procedure, how about we build a little front end to show off the work we’ve done so far on this proof of concept? That will also make things easier to test out and let us get into the mindset of the user. There are a ton of options here, lots of folks like Spring and Spring Boot. Others are more hipsters and into Micronaut. I am even more of a hipster and prefer to use Jooby, but it doesn’t really matter. We’ll be using Cypher, the Neo4j Drivers and the Stored Procedures we build along the way so technically you can do this in just about any language.
Continue reading →

Tagged , , , , , , , ,

Building a Chat Bot in Neo4j Part 2

In part one our this building a chatbot series, we figured out how to use OpenNLP to “hear” what a user is saying and figure out both their intent and any entities they may have mentioned. Today we’re going to learn how to use Neo4j to talk back… like an impudent child.

Continue reading →

Tagged , , , , , , , , ,

Building a Chat Bot in Neo4j

Last year eBay built a chatbot using Neo4j. Unfortunately we have grown so big I didn’t get a chance to work on that project and kinda feel left out. So I decided I’m going to build my own chatbot with Neo4j. As usual I’ve never done this before, have very little idea what I’m doing, have no team, and have barely any time to get this done. So with those disclaimers out of the way, let’s see what we can do.
Continue reading →

Tagged , , , , , , , ,

The Real Property Graph

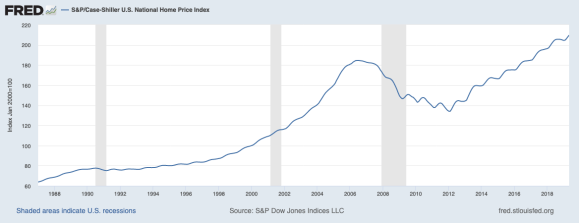
Is not that thing above. That’s a Chart, not a Graph. But anyway…Neo4j is designed to support the property graph model natively. There are a host of other technologies that can bolt-on a “graph layer” of some kind. However it doesn’t make them a graph database. It’s like adding a rear spoiler to a van, sure it may look cool… or ridiculous, but it won’t make it a race car. Don’t fall for it. If you need fast graph queries, use a real graph database. But today we won’t talk about that. Instead we’re going to talk about the real property graph…
Continue reading →

Tagged , , , , , , ,